We are entering a new phase of AI adoption.
Teams are no longer just using AI to generate text, write code or automate isolated tasks. They are asking it to connect to company data, analyse information across different systems, identify patterns and build dashboards that support business decisions.
And this changes the problem.
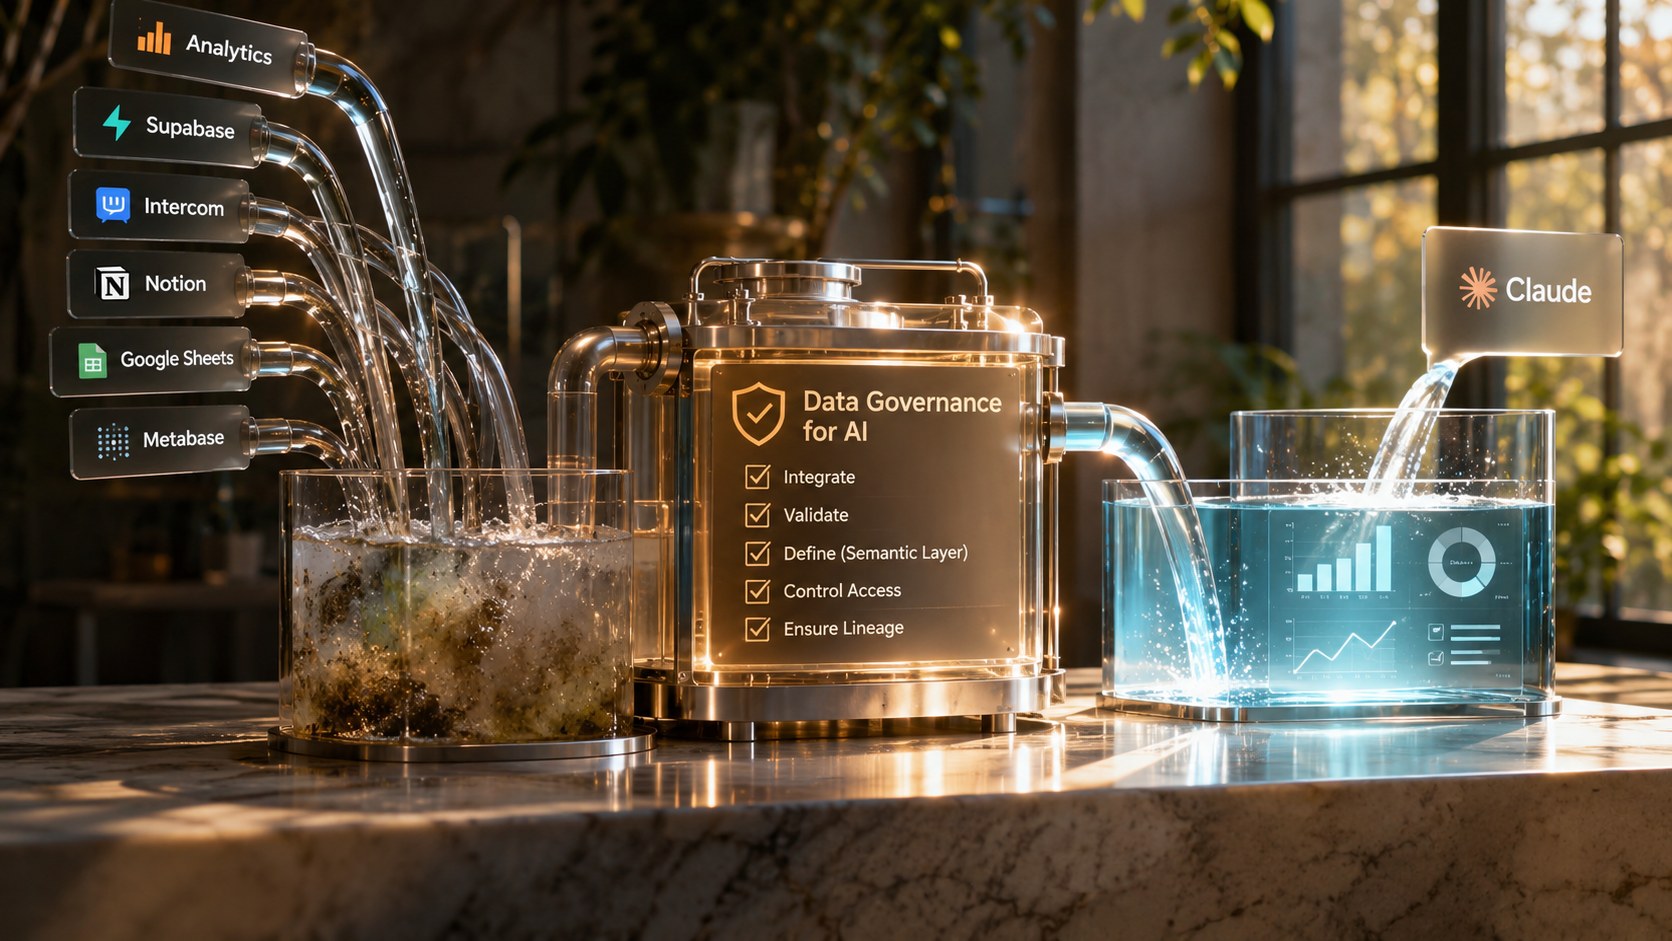
Imagine asking Claude to build a dashboard using data from Supabase, Google Analytics, Intercom, Notion and Google Sheets.
Technically, this is becoming increasingly easy. Connect the sources, provide a prompt, and let AI do the work.
But there is a question we should be asking before celebrating the result:
How do we know the data behind that dashboard can actually be trusted?
Because connecting data is not the same as understanding it.
Different systems have different structures, definitions, business rules and levels of data quality.
A user in Supabase might not mean the same thing as a user in Google Analytics. An active user might have a completely different definition across Product, Marketing and Customer Success.
When AI combines these sources, it has to interpret those differences.
And if the underlying data is inconsistent, incomplete or poorly documented, AI can produce something that looks perfectly reasonable while telling the wrong story.
This is where I believe the next architectural challenge lies.
From connecting data to governing data for AI
For years, Data Engineering and Data Governance have focused on making data accessible, structured, documented and reliable.
Now, we need to take that one step further.
We need to make data understandable and trustworthy for AI systems.
This means moving beyond direct connections between AI tools and individual data sources towards a governed data architecture.
One where different components work together:
- Data Integration: bringing information from different systems into a consistent environment.
- Data Quality: validating structures, relationships, completeness and freshness.
- Data Governance: establishing ownership, access policies, classification and lineage.
- Semantic Layer: defining what business metrics actually mean, how they are calculated and which definitions should be used.
- AI Access Layer: exposing trusted data and business context to AI agents through controlled interfaces such as APIs and MCP.
The goal is not to centralise everything just for the sake of centralisation.
It is to establish a reliable layer between enterprise data and the AI systems consuming it.
The Semantic Layer: giving data business meaning
One component deserves particular attention: the Semantic Layer.
Consider a simple question:
How many active users did we have last month?
Before calculating anything, we need to agree on what an active user actually is.
Does logging into the platform count? Does a specific product interaction need to happen? Should test accounts be excluded? Which source is authoritative?
These are not questions an AI model should answer by guessing.
They are business definitions that need to exist independently of the model.
A Semantic Layer makes these definitions explicit, reusable and consistent across different tools and applications.
Instead of asking AI to figure out how a metric should be calculated every time, we give it access to an established definition.
This is a fundamental shift: from AI interpreting raw data to AI consuming governed business knowledge.
The role of MCP and the next generation of data architecture
With the emergence of Model Context Protocol (MCP), we are also seeing new possibilities for connecting AI systems to enterprise environments.
But connecting an agent to a database through MCP does not automatically make that integration trustworthy.
We still need authentication, authorisation, data validation, business context and auditability.
I believe we will increasingly see architectures where AI agents do not query every source independently.
Instead, they interact with a governed data layer that exposes approved datasets, certified metrics and controlled query capabilities.
The AI becomes a consumer of trusted information, rather than the component responsible for deciding what the data means.
From AI-generated dashboards to AI-ready data
I think this distinction will become increasingly important as organisations move from AI experimentation towards enterprise adoption.
Building a dashboard with AI is impressive.
Building a dashboard that produces consistent, explainable and reproducible results is a different challenge.
And that challenge cannot be solved by choosing a better model or writing a better prompt.
It requires architecture.
It requires Data Engineering, Data Governance and AI Architecture to work together.
Because ultimately, the value of AI in an enterprise will not depend only on how intelligent its models become.
It will also depend on how well the organisation prepares, structures and governs the information those models rely on.
The future is not just about making enterprise data accessible to AI. It is about making enterprise data trustworthy for AI.
No responses yet